Finding the best desktop GPU for LLM fine tuning requires balancing raw performance, memory capacity, and compatibility with AI workflows. The NVIDIA RTX PRO 5000 Blackwell stands out as the overall top choice thanks to its high memory bandwidth and robust AI features. For those seeking a more cost-effective yet capable option, the NVIDIA RTX A5500 offers excellent price-to-performance, especially for professional workloads. Meanwhile, the GIGABYTE GeForce RTX 5080 Gaming OC provides strong gaming performance with AI capabilities but may fall short for extensive professional fine-tuning tasks. These tradeoffs reflect the core tension: higher-end cards deliver greater performance but come at a premium, while more affordable options might lack some specialized features. Keep reading for a detailed breakdown of the best GPUs for your LLM fine tuning needs in 2026.

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Key Takeaways
- High memory capacity (24GB-96GB) is essential for large language model fine tuning, favoring professional-grade GPUs.
- NVIDIA cards dominate this space, but AMD options like the Radeon RX 9070 XT offer competitive performance at a different price point.
- Memory bandwidth and PCIe version (4.0 vs 5.0) impact data transfer speeds, which matter during intensive training sessions.
- Professional GPUs (A5500, RTX A6000) excel in stability and driver support but come with a higher price tag.
- Balance between performance and price remains critical—mid-range cards like the RTX 5080 OC may suffice for many but won’t match top-tier models for large models.
| PNY NVIDIA RTX PRO 5000 Blackwell 48GB GDDR7 Graphics Card |  | Best Overall — High Memory Capacity for Demanding Fine Tuning | Memory: 48 GB GDDR7 | Monitors Supported: 4 | Max Display Resolution: 7680 x 4320 | VIEW LATEST PRICE | See Our Full Breakdown |
| NVIDIA RTX PRO 4000 Blackwell Graphics Card – 24GB GDDR7 ECC Memory, PCIe 5.0 x16, 4X DisplayPort 2.1b, Single Slot Full Height AI Workstation GPU |  | Best for Professional AI Workstations — Compact and Powerful | Memory: 24GB GDDR7 ECC | Architecture: Blackwell | Interface: PCIe 5.0 x16 | VIEW LATEST PRICE | See Our Full Breakdown |
| NVIDIA Tesla V100 32GB PCIe 3.0 x16 Passive GPU Accelerator (Renewed) |  | Best for Enterprise-Grade Deep Learning and HPC | Memory: 32GB HBM2 ECC | CUDA Cores: 4,608 | Tensor Cores: 640 | VIEW LATEST PRICE | See Our Full Breakdown |
| PNY NVIDIA RTX PRO 6000 Blackwell MAX-Q Workstation Edition Dual Fan 96GB GDDR7 |  | Best High-Memory Workstation GPU — Dual Fan Cooling | Memory: 96GB GDDR7 | Cooling System: Dual Fan | Edition: Workstation | VIEW LATEST PRICE | See Our Full Breakdown |
| ASUS Turbo Radeon AI PRO R9700 32GB Graphics Card for AI Workloads |  | Best for Large AI Models — AMD RDNA 4 Architecture | Graphics Coprocessor: AMD Radeon AI PRO R9700 | VRAM: 32 GB GDDR6 | AI Accelerators: 128 | VIEW LATEST PRICE | See Our Full Breakdown |
| GIGABYTE GeForce RTX 5080 Gaming OC 16G Graphics Card |  | Best Overall for High-End LLM Fine Tuning | Architecture: NVIDIA Blackwell | Memory: 16GB GDDR7 | Memory Interface: 256-bit | VIEW LATEST PRICE | See Our Full Breakdown |
| PNY NVIDIA RTX A5500 Professional Graphics Card 24GB GDDR6 |  | Best for Professional-Grade Model Development | GPU processor: NVIDIA RTX A5500 | CUDA cores: 10240 | Memory: 24GB GDDR6 ECC | VIEW LATEST PRICE | See Our Full Breakdown |
| NVIDIA RTX PRO 4000 Blackwell |  | Best Compact Professional GPU for Versatile Workflows | Architecture: Blackwell | Memory: 32GB GDDR7 | CUDA Cores: 10496 | VIEW LATEST PRICE | See Our Full Breakdown |
| ASUS TUF Gaming GeForce RTX 5080 16GB GDDR7 OC Edition | 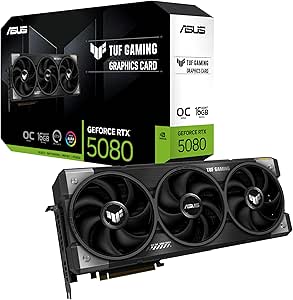 | Best for Enthusiasts Seeking Durability and Performance | Memory: 16GB GDDR7 | Architecture: NVIDIA Blackwell | Boost Clock: 2730 MHz | VIEW LATEST PRICE | See Our Full Breakdown |
| PNY NVIDIA RTX A5000 Professional Graphics Card 24GB GDDR6 |  | Best for Budget-Conscious Professional Fine Tuning | GPU Processor: NVIDIA RTX A5000 | CUDA Cores: 8192 | Memory: 24GB GDDR6 ECC | VIEW LATEST PRICE | See Our Full Breakdown |
| PNY NVIDIA RTX A6000 |  | Best Overall for Professional Large-Scale Fine Tuning | Architecture: Ampere | CUDA Cores: Not specified | RT Cores: Second-Generation, up to 2X throughput | VIEW LATEST PRICE | See Our Full Breakdown |
| ASRock Radeon AI PRO R9700 Creator 32GB Professional Graphics Card |  | Best for AI Developers Needing PCIe 5.0 and Large VRAM | Graphics Coprocessor: AMD Radeon AI PRO R9700 | Memory: 32 GB GDDR6 | GPU Clock Speed: 2920 MHz | VIEW LATEST PRICE | See Our Full Breakdown |
| ASRock Intel Arc Pro B70 Creator 32GB Workstation Graphics Card, Xe2-HPG |  | Best for Multi-GPU Workstations and High-Res Visualization | GPU Architecture: Intel Xe2-HPG | Memory: 32GB GDDR6 | Memory Bus: 256-bit | VIEW LATEST PRICE | See Our Full Breakdown |
| GIGABYTE Radeon RX 9070 XT Gaming OC 16G Graphics Card |  | Best for High-Resolution Professional and Gaming Use | Graphics Coprocessor: AMD Radeon RX 9070 XT | RAM: 16 GB | GPU Clock Speed: 3060 MHz | VIEW LATEST PRICE | See Our Full Breakdown |
| desktop gpu for llm fine tuning | Memory |
|---|---|
| PNY NVIDIA RTX PRO 5000 Blackw | 48 GB GDDR7 |
| NVIDIA RTX PRO 4000 Blackwell | 24GB GDDR7 ECC |
| NVIDIA Tesla V100 32GB PCIe 3. | 32GB HBM2 ECC |
| PNY NVIDIA RTX PRO 6000 Blackw | 96GB GDDR7 |
| ASUS Turbo Radeon AI PRO R9700 | — |
| GIGABYTE GeForce RTX 5080 Gami | 16GB GDDR7 |
| PNY NVIDIA RTX A5500 Professio | 24GB GDDR6 ECC |
| NVIDIA RTX PRO 4000 Blackwell | 32GB GDDR7 |
| ASUS TUF Gaming GeForce RTX 50 | 16GB GDDR7 |
| PNY NVIDIA RTX A5000 Professio | 24GB GDDR6 ECC |
| PNY NVIDIA RTX A6000 | 48 GB GDDR6 |
| ASRock Radeon AI PRO R9700 Cre | 32 GB GDDR6 |
| ASRock Intel Arc Pro B70 Creat | 32GB GDDR6 |
| GIGABYTE Radeon RX 9070 XT Gam | — |
More Details on Our Top Picks
PNY NVIDIA RTX PRO 5000 Blackwell 48GB GDDR7 Graphics Card
This model stands out for its massive 48GB GDDR7 memory, making it ideal for training and fine-tuning large language models that demand substantial VRAM. Compared with the NVIDIA RTX PRO 4000, it offers nearly double the memory, which can significantly reduce training bottlenecks for very large models. Its support for up to four monitors and 8K resolution enhances multi-tasking and detailed visualization. The main tradeoff is that this card lacks detailed info on cooling and power, which could lead to higher operational costs or installation challenges. It is best suited for enterprise environments or research labs working on extremely large datasets where maximum memory is critical. However, casual or smaller-scale AI projects will find this overkill and too expensive.
Pros:- Exceptional 48GB GDDR7 memory capacity for large models
- Supports multiple monitors and high-resolution outputs
- PCIe 5.0 interface ensures fast data transfer
Cons:- Lack of cooling and power details could complicate setup
- High cost limits accessibility for smaller projects
Best for: Research institutions or enterprise AI teams working on large-scale language model fine-tuning that require maximum VRAM and multi-monitor support.
Not ideal for: Small startups or individual developers focusing on smaller models, due to its high cost and over-specification.
- Memory:48 GB GDDR7
- Monitors Supported:4
- Max Display Resolution:7680 x 4320
- Host Interface:PCI Express 5.0 x16
- Color:Black
- Potential Drawback:High cost, limited cooling info
Our verdict“This card is best for large-scale, resource-intensive fine tuning where maximum VRAM and multi-monitor capability justify the investment.”
NVIDIA RTX PRO 4000 Blackwell Graphics Card – 24GB GDDR7 ECC Memory, PCIe 5.0 x16, 4X DisplayPort 2.1b, Single Slot Full Height AI Workstation GPU
This pick makes sense for professionals needing a balance of high performance and compact form factor. Its 24GB GDDR7 ECC memory is well-suited for AI training and fine tuning, comparable to the 48GB on the RTX PRO 5000 but with a smaller footprint. The PCIe 5.0 interface ensures fast data movement, similar to the higher-end options, but at a more accessible price point. With four DisplayPort 2.1b outputs, it supports multi-monitor setups ideal for visualization and concurrent tasks. Compared to the Tesla V100, it offers similar ECC features but in a more user-friendly, workstation-ready package. The main tradeoff is that it’s likely more expensive than consumer-grade GPUs and its single-slot design can limit airflow, requiring careful case planning. It’s perfect for dedicated AI workstations that need reliable performance without enterprise server hardware.
Pros:- High-performance 24GB GDDR7 ECC memory
- PCIe 5.0 support for fast data transfer
- Multiple DisplayPort outputs for multi-monitor setups
Cons:- Likely costly, especially for enterprise features
- Single slot design may limit airflow and cooling options
Best for: AI professionals or researchers who need a compact, reliable GPU with ECC memory for fine tuning large models in workstations.
Not ideal for: Enthusiasts or gamers seeking gaming performance or multi-GPU configurations, due to its focus on stability and ECC features.
- Memory:24GB GDDR7 ECC
- Architecture:Blackwell
- Interface:PCIe 5.0 x16
- Display Outputs:4X DisplayPort 2.1b
- Form Factor:Single Slot Full Height
- Use Case:AI Workstation
Our verdict“This card is ideal for professional AI workflows requiring a compact, ECC-enabled GPU with high data throughput.”
NVIDIA Tesla V100 32GB PCIe 3.0 x16 Passive GPU Accelerator (Renewed)
The Tesla V100 is designed primarily for enterprise and scientific computing, with 32GB of high-bandwidth HBM2 memory and support for multi-precision workloads. Compared to the newer RTX options, it offers a different focus: optimized for multi-GPU scaling and high precision calculations, making it less suited for straightforward fine-tuning but excellent for large, distributed training environments. Its passive cooling emphasizes enterprise deployments where airflow is managed separately. The NVLink support and 900 GB/s bandwidth make it a powerhouse for large-scale, multi-GPU setups, but it’s not an ideal choice for individual developers or small labs due to its enterprise focus and high price. It’s best for those running multi-GPU clusters in data centers rather than desktop setups.
Pros:- Massive 32GB HBM2 high-bandwidth memory
- Supports multi-GPU scaling via NVLink
- Validated for enterprise server platforms
Cons:- Passive cooling requires excellent airflow setup
- Designed for servers, not for desktop use
Best for: Large research labs or enterprise environments running multi-GPU clusters for deep learning and scientific computing.
Not ideal for: Small-scale AI developers or hobbyists, because it’s designed for server deployment and requires specialized infrastructure.
- Memory:32GB HBM2 ECC
- CUDA Cores:4,608
- Tensor Cores:640
- Memory Bandwidth:900 GB/s
- Interface:PCIe 3.0 x16
- TDP:250W
Our verdict“This GPU excels in large-scale, multi-GPU environments where enterprise-grade performance outweighs desktop convenience.”
PNY NVIDIA RTX PRO 6000 Blackwell MAX-Q Workstation Edition Dual Fan 96GB GDDR7
This GPU is tailored for intensive professional workloads, especially where large VRAM helps with massive models. The 96GB GDDR7 memory surpasses most options, similar in purpose to the RTX PRO 5000 but with a focus on workstation reliability. Its dual fan cooling improves thermal performance during prolonged workloads, making it suitable for sustained fine-tuning sessions. While the high memory capacity and cooling system are advantages, the size and likely high cost mean it isn’t suitable for small or casual setups. Compared to the RTX PRO 4000, it offers significantly more VRAM, making it better for extremely large models, but at a premium price. This is a choice for high-end professional environments needing maximum VRAM and stability.
Pros:- Massive 96GB GDDR7 VRAM for large models
- Dual fan cooling enhances thermal stability
- Designed for professional, sustained workloads
Cons:- Expensive compared to mid-range options
- Large size may require significant case space
Best for: Large AI research teams or professional studios working on very large language models requiring maximum VRAM and robust cooling.
Not ideal for: Individual hobbyists or small startups with limited budgets, due to its high price and physical size.
- Memory:96GB GDDR7
- Cooling System:Dual Fan
- Edition:Workstation
- Model:RTX PRO 6000 Blackwell MAX-Q
- Form Factor:Workstation Edition
- Use Case:High-end Professional Workloads
Our verdict“This GPU is ideal for demanding professional workstations that need exceptional VRAM and cooling for continuous fine tuning.”
ASUS Turbo Radeon AI PRO R9700 32GB Graphics Card for AI Workloads
This AMD-based GPU targets large AI models with its 32GB GDDR6 VRAM and 128 dedicated AI accelerators, making it especially suitable for handling complex, multi-GPU setups. Compared to NVIDIA’s offerings, it emphasizes real-time AI processing with dedicated accelerators and thermal durability features, making it a solid choice for long-term projects. Its PCIe 5.0 support aligns with high-speed data transfer requirements, but it’s primarily designed for AI workloads rather than gaming or general-purpose computing. The card’s power consumption and cost are higher, which could be a concern for smaller setups. It’s best for organizations prioritizing AMD architecture and multi-GPU scaling for large language model fine tuning, where specialized AI features matter most.
Pros:- Large 32GB VRAM suitable for massive models
- Supports multi-GPU scaling with PCIe 5.0
- Enhanced thermal management for reliability
Cons:- High power needs and cost
- Designed mainly for AI, not gaming
Best for: Teams working on large-scale AI projects with multi-GPU configurations that value AMD’s AI acceleration features and large VRAM.
Not ideal for: Gamers or casual users, since the card is optimized for AI workloads and not gaming performance.
- Graphics Coprocessor:AMD Radeon AI PRO R9700
- VRAM:32 GB GDDR6
- AI Accelerators:128
- GPU Clock Speed:2940 MHz
- Video Output:2 x HDMI 2.1b
- Support for:Multi-GPU PCIe 5.0
Our verdict“This AMD GPU fits large AI projects that require substantial VRAM and multi-GPU scalability with a focus on AI-specific features.”
GIGABYTE GeForce RTX 5080 Gaming OC 16G Graphics Card
The GIGABYTE GeForce RTX 5080 Gaming OC stands out for its cutting-edge NVIDIA Blackwell architecture paired with 16GB of GDDR7 memory, offering robust performance for complex LLM fine-tuning tasks. Compared to the ASUS TUF Gaming RTX 5080, it provides a slightly higher clock speed and a more aggressive cooling system, making it better suited for sustained workloads. However, it demands a high-capacity power supply and a spacious case due to its size and power draw, which could be a barrier for smaller builds. This card is a strong choice for those needing maximum performance with less concern for cost or size constraints.
Pros:- Leverages the latest NVIDIA Blackwell architecture for superior compute efficiency
- Large 16GB GDDR7 memory supports extensive model fine-tuning
- Advanced WINDFORCE cooling system ensures thermal stability under load
Cons:- High power consumption necessitates a premium power supply
- Size may require case upgrades or adjustments
Best for: Power users with large, well-ventilated cases and high-capacity PSUs seeking top-tier performance for extensive fine-tuning.
Not ideal for: Casual hobbyists or users with limited case space and modest power supplies, as its size and power requirements are substantial.
- Architecture:NVIDIA Blackwell
- Memory:16GB GDDR7
- Memory Interface:256-bit
- PCIe Version:PCIe 5.0
- Cooling System:WINDFORCE
Our verdict“This card suits enthusiasts and professionals demanding maximum performance for large-scale LLM fine-tuning projects.”
PNY NVIDIA RTX A5500 Professional Graphics Card 24GB GDDR6
The PNY NVIDIA RTX A5500 offers 24GB of ECC GDDR6 memory, making it ideal for high-precision, large-scale model fine-tuning where stability and accuracy are paramount. Its PCIe 4.0 x16 interface supports fast data transfer, comparable to the RTX 5080 but slightly behind in bandwidth. While it excels in professional workflows, its high price and professional design mean it’s less appealing for casual or gaming-focused users. Compared with the RTX PRO 4000, the A5500 provides more memory without sacrificing much in transfer speeds, but it isn’t optimized for gaming or lightweight tasks.
Pros:- Massive 24GB GDDR6 ECC memory ensures data integrity for long training sessions
- Supports 8K resolution for high-quality visualization
- Quiet active fan maintains thermal stability during intensive workloads
Cons:- High cost limits accessibility to professional environments
- Requires compatible PCIe slots and sufficient power supply
Best for: Data scientists and AI researchers prioritizing large, stable memory pools and high-precision compute for fine-tuning models professionally.
Not ideal for: Gamers or hobbyists who need more general-purpose GPU performance, as its design targets professional workflows and it’s costly.
- GPU processor:NVIDIA RTX A5500
- CUDA cores:10240
- Memory:24GB GDDR6 ECC
- System Interface:PCI-Express 4.0 x16
- Display Outputs:4x DisplayPort
Our verdict“This card is best suited for professional AI development where large, reliable memory is critical.”
NVIDIA RTX PRO 4000 Blackwell
The NVIDIA RTX PRO 4000 Blackwell excels in delivering 32GB of GDDR7 memory within a compact 4.4 x 10.5-inch form factor, making it highly suitable for workstation environments with space constraints. Its advanced ray tracing and AI cores support complex model fine-tuning with realistic simulation capabilities. When compared to the RTX A5500, it offers more memory in a smaller package, but at a higher price point, and is primarily aimed at professionals who need both power and space efficiency. While not ideal for gaming, its versatile connectivity and high resolution support make it a flexible option for demanding workflows.
Pros:- High 32GB GDDR7 memory supports large datasets and models
- Compact size fits into diverse system configurations
- Supports ultra-high resolutions up to 8K at 240Hz
Cons:- Expensive compared to similar-sized consumer cards
- Designed for professional use, less tailored for gaming
Best for: Professionals requiring high memory capacity in a small form factor for intensive model fine-tuning and AI workflows.
Not ideal for: Enthusiasts seeking budget-friendly or gaming-centric solutions, as this card is tailored for professional tasks and comes at a premium price.
- Architecture:Blackwell
- Memory:32GB GDDR7
- CUDA Cores:10496
- Memory Bandwidth:896 GB/s
- Display Support:Up to 8K at 240Hz
Our verdict“This GPU is best for professionals needing high memory capacity and space-efficient design for demanding AI tasks.”
ASUS TUF Gaming GeForce RTX 5080 16GB GDDR7 OC Edition
The ASUS TUF Gaming RTX 5080 OC Edition combines high performance with military-grade durability, making it suitable for intensive LLM fine-tuning over extended periods. Its NVIDIA Blackwell architecture with DLSS 4 boosts throughput, while the triple Axial-tech fans and phase-change thermal pad ensure effective cooling. Compared to the GIGABYTE RTX 5080, it offers similar core performance but emphasizes robustness and longevity, often at a higher cost due to premium components. Its demanding 850W power requirement and large size can limit compatibility with smaller or less powerful systems.
Pros:- NVIDIA Blackwell architecture with DLSS 4 for enhanced performance
- Military-grade components ensure durability
- Effective cooling with three Axial-tech fans
Cons:- Requires an 850W power supply, increasing system costs
- Large physical size may not fit in all cases
Best for: Enthusiasts and professionals who need a durable, high-performance GPU capable of sustained workloads with reliable cooling.
Not ideal for: Casual users or those with smaller cases and limited power supplies, due to size and power demands.
- Memory:16GB GDDR7
- Architecture:NVIDIA Blackwell
- Boost Clock:2730 MHz
- Dimensions:348mm length, 3.6 slots
- Power Requirement:850W PSU, 16-pin connector
Our verdict“This card is best for high-end users who prioritize durability and sustained performance in demanding fine-tuning tasks.”
PNY NVIDIA RTX A5000 Professional Graphics Card 24GB GDDR6
The PNY NVIDIA RTX A5000 offers 24GB of GDDR6 with ECC, making it a compelling choice for those focused on large model training with accuracy. Its PCIe 4.0 interface offers decent data throughput, though slightly less than PCIe 5.0 options like the RTX PRO 4000. It supports 8K resolution, similar to higher-end options, but its single-fan design and professional focus mean it’s less suited for intensive gaming or casual use. When compared with the RTX A5500, it’s a more affordable alternative, though still costly for non-professionals.
Pros:- Massive 24GB GDDR6 ECC memory supports large models and datasets
- Supports high resolutions up to 8K
- Quiet operation with active cooling
Cons:- Designed for professional workflows, limiting gaming performance
- Higher price may be prohibitive for casual or smaller scale projects
Best for: Research labs and professional developers who need large memory pools at a more accessible price point.
Not ideal for: Enthusiasts or gamers seeking high frame rates or casual workloads; it’s optimized for professional stability and accuracy.
- GPU Processor:NVIDIA RTX A5000
- CUDA Cores:8192
- Memory:24GB GDDR6 ECC
- Interface:PCI-Express 4.0 x16
- Maximum Resolution:7680×4320
Our verdict“This GPU is ideal for professional environments requiring large, reliable memory without the cost of top-tier flagship models.”
PNY NVIDIA RTX A6000
The NVIDIA RTX A6000 stands out for its exceptional capacity to handle massive datasets and complex models, thanks to its massive 48GB GDDR6 memory and advanced Ampere architecture. Compared to the GIGABYTE Radeon RX 9070 XT Gaming OC, which offers only 16GB of VRAM, the A6000 provides unparalleled memory capacity, making it ideal for large language model (LLM) fine tuning. Its RT and Tensor Cores accelerate both rendering and AI tasks, but this performance comes with a high cost and significant power requirements. While it’s primarily designed for professional workstations, those with large-scale models will find its capabilities justify the expense. However, it’s overkill for smaller projects or casual use, where budget and space become limiting factors.
Pros:- Massive 48GB GDDR6 memory handles very large datasets effortlessly
- Advanced RT and Tensor Cores accelerate complex AI and rendering workloads
- Supports NVLink for scalable memory expansion
Cons:- High purchase price makes it inaccessible for most individual users
- Heavy and power-hungry, requiring substantial cooling and PSU capacity
Best for: Large research labs or enterprises working with multi-billion parameter models requiring maximum VRAM and compute power.
Not ideal for: Individual hobbyists or small startups with budget constraints, since the cost and space needs are substantial.
- Architecture:Ampere
- CUDA Cores:Not specified
- RT Cores:Second-Generation, up to 2X throughput
- Tensor Cores:Third-Generation with TF32 and structural sparsity
- Memory:48 GB GDDR6
- Memory Scalability:Up to 96 GB with NVLink
Our verdict“This GPU is best suited for large-scale AI research institutions and professionals with demanding data needs who can justify the investment.”
ASRock Radeon AI PRO R9700 Creator 32GB Professional Graphics Card
The ASRock Radeon AI PRO R9700 excels in AI development and large dataset processing, offering 32GB GDDR6 memory and PCIe 5.0 support, which ensures high data transfer speeds. When compared to the PNY NVIDIA RTX A6000, it provides a more affordable, yet still capable, professional alternative with ample VRAM for large models. Its RDNA 4 architecture with AI accelerators enhances performance for compute-heavy tasks, although it’s primarily targeted at workstation and server environments, making it less suitable for casual or gaming users. Its single blower cooling can be noisy under load, and compatibility with some professional software should be verified before purchase. Overall, it delivers excellent value for AI practitioners with large models and high bandwidth needs.
Pros:- High 32GB GDDR6 VRAM supports large AI models and datasets
- PCIe 5.0 support ensures maximum bandwidth for data transfer
- Durable build with metal shroud and backplate for 24/7 operation
Cons:- Designed for professional use, potentially overkill for casual users
- Single blower cooling can generate noise during intensive workloads
Best for: AI researchers and data scientists working on large models in professional or enterprise environments who need PCIe 5.0 bandwidth.
Not ideal for: Casual hobbyists or gamers, since its professional focus and potential noise level may be overkill and disruptive for typical home setups.
- Graphics Coprocessor:AMD Radeon AI PRO R9700
- Memory:32 GB GDDR6
- GPU Clock Speed:2920 MHz
- Video Output Interface:DisplayPort 2.1a
- Graphics Ram Type:GDDR6
- Maximum Resolution:7680 x 4320
Our verdict“This card suits AI developers needing high bandwidth and large VRAM, especially in enterprise settings where professional-grade hardware is justified.”
ASRock Intel Arc Pro B70 Creator 32GB Workstation Graphics Card, Xe2-HPG
The ASRock Intel Arc Pro B70 offers a compelling option for multi-GPU setups and high-resolution visualization, with 32GB GDDR6 VRAM and PCIe 5.0 support. When compared with the PNY NVIDIA RTX A6000, it provides a more balanced price point while supporting multi-monitor configurations via four DisplayPort 2.1 outputs. Its vapor chamber cooling and phase-change materials help maintain stability under sustained workloads, making it ideal for complex rendering and AI tasks. However, its size and power requirements demand careful compatibility checks. Its professional focus makes it less appealing for casual users or gaming, but for multi-GPU AI or visualization tasks, it provides a reliable, scalable platform.
Pros:- Supports multi-GPU configurations for scalable performance
- High 32GB GDDR6 VRAM supports large datasets and models
- Multiple high-resolution outputs for demanding visualization tasks
Cons:- Requires careful compatibility checks for power supply and chassis
- Designed for professional use, limiting appeal for casual or gaming users
Best for: Workstation environments with multi-GPU configurations and high-resolution visualization needs, especially in AI, rendering, and scientific computing.
Not ideal for: Enthusiasts or gamers who prioritize gaming performance over professional multi-GPU or high-res display workflows, due to its professional features and form factor.
- GPU Architecture:Intel Xe2-HPG
- Memory:32GB GDDR6
- Memory Bus:256-bit
- Memory Speed:19 Gbps
- Engine Clock:2540 MHz
- Display Outputs:4x DisplayPort 2.1
Our verdict“This GPU is tailored for multi-GPU workstation setups that demand high VRAM and multi-display capabilities in professional contexts.”
GIGABYTE Radeon RX 9070 XT Gaming OC 16G Graphics Card
The GIGABYTE Radeon RX 9070 XT Gaming OC offers a balanced mix of gaming and professional performance with 16GB GDDR6 and support for 8K resolutions, making it versatile for both high-end gaming and professional workloads. Compared with the PNY NVIDIA RTX A6000, which excels in raw capacity and AI acceleration, this card provides a more accessible option for those needing high resolutions without the massive VRAM. Its robust cooling system supports stable operation at high clock speeds, but its size and higher power draw could be limiting in smaller builds. While it’s less specialized for AI training than the NVIDIA options, it delivers solid performance at a more approachable price point, especially for users balancing gaming and professional tasks.
Pros:- Supports ultra-high resolutions up to 8K for detailed visual work
- Powerful cooling system for stable performance under load
- Versatile for gaming and professional applications
Cons:- Limited VRAM (16GB) compared to professional GPUs, less suitable for very large models
- High power consumption and large size may require significant case space
Best for: Advanced users seeking high-resolution output for visualizations or mixed workloads with a focus on gaming and moderate AI tasks.
Not ideal for: Pure AI researchers or large-scale fine-tuning projects requiring maximum VRAM and Tensor core acceleration, where NVIDIA options are preferable.
- Graphics Coprocessor:AMD Radeon RX 9070 XT
- RAM:16 GB
- GPU Clock Speed:3060 MHz
- Video Output Interface:DisplayPort
- Graphics RAM Type:GDDR6
- Maximum Resolution:7680 x 4320
Our verdict“This card suits users who need high-resolution support and balanced performance for both gaming and moderate professional workloads, but it’s less ideal for very large AI models.”

How We Picked
Our evaluation focused on performance metrics like VRAM size, memory bandwidth, and CUDA core counts, which directly influence training speed and capacity. Compatibility with common AI frameworks and PCIe standards was also considered, ensuring these GPUs integrate smoothly into existing setups. We prioritized cards designed for professional or AI workloads, balancing raw power with reliability and driver support. Price-to-performance ratios played a key role in ranking, aiming to identify options that deliver substantial compute capability without unnecessary expense. Ultimately, these selections represent a blend of cutting-edge hardware and value-driven choices suitable for serious LLM fine tuning in 2026.Factors to Consider When Choosing Best Desktop Gpu For Llm Fine Tuning
Choosing the right GPU for LLM fine tuning involves several critical considerations beyond raw specs. Understanding your workload size, budget constraints, and compatibility needs will help you avoid costly mistakes. The following factors outline key points to focus on when selecting a GPU that aligns with your training goals and infrastructure.Memory Capacity and Bandwidth
Large language models demand significant VRAM—typically 24GB or more—to handle extensive datasets and complex models efficiently. Higher memory bandwidth ensures faster data transfer between GPU and memory, reducing bottlenecks during training. Opting for a GPU with ample VRAM and bandwidth provides smoother training experiences, especially with larger models. However, note that higher memory specs usually come with increased cost, so balance your needs against your budget.
Compatibility and PCIe Standards
Ensuring your GPU supports PCIe 4.0 or PCIe 5.0 is vital for maximizing data transfer speeds, especially when working with large datasets or multiple GPUs. Compatibility with your motherboard and power supply also matters; professional-grade cards often require specialized connections and cooling solutions. Choosing a GPU aligned with your system’s PCIe version and physical space will prevent integration issues and optimize performance.
Performance Metrics and Framework Support
Key performance indicators like CUDA cores, tensor cores, and floating-point operations directly impact training speed. For LLM fine tuning, prioritize GPUs optimized for AI workloads, which often feature dedicated tensor cores. Compatibility with popular frameworks such as TensorFlow or PyTorch is crucial for a seamless experience. Be wary of cards that lack driver support or stability in professional environments, as these can hinder long-term productivity.
Price and Total Cost of Ownership
While top-tier GPUs offer unmatched performance, their high price can be prohibitive. Consider the total cost, including potential upgrades to your system or cooling solutions. Sometimes, mid-range cards provide sufficient power for most fine-tuning tasks without breaking the bank. Avoid overspending on features you won’t utilize, but also recognize that cheaper options may lack durability or professional support, leading to higher long-term costs.
Noise, Power Consumption, and Cooling
Effective cooling and power efficiency influence your system’s stability and operational costs. High-performance GPUs can generate significant heat and noise, especially under full load. Investing in a good cooling solution and considering power supply capacity ensures reliable operation during long training sessions. Quiet and efficient cards are preferable if your workspace requires low noise levels or if you’re using the GPU in a shared environment.
Frequently Asked Questions
Can I use gaming GPUs for LLM fine tuning?
Yes, gaming GPUs can handle fine-tuning smaller models effectively, and they are often more affordable. However, they typically lack the extensive VRAM and professional driver support needed for larger models or long training runs. Gaming cards may also have limited optimization for AI workloads, leading to potential stability issues over time. For serious or large-scale fine tuning, professional-grade GPUs tend to offer more reliability and better performance consistency.
Is VRAM more important than raw GPU compute power for LLM fine tuning?
In large language model training, VRAM tends to be the most critical factor because it directly affects the size of models and datasets you can work with simultaneously. While raw compute power (CUDA cores, tensor cores) accelerates processing, insufficient VRAM results in frequent data swapping or inability to load large models. Balancing both aspects is ideal, but for extremely large models, VRAM capacity usually takes precedence.
What is the benefit of PCIe 5.0 over PCIe 4.0 in AI workloads?
PCIe 5.0 doubles the data transfer rate of PCIe 4.0, which can reduce bottlenecks during data-intensive training sessions. This faster interface allows for quicker loading of datasets and model weights, especially when multiple GPUs are used together. However, many existing systems and GPUs still primarily support PCIe 4.0, so upgrading to PCIe 5.0 may require additional system investments and compatibility checks.
Are professional GPUs worth the extra cost for LLM fine tuning?
Professional GPUs often provide enhanced driver support, increased stability, and larger VRAM capacities, making them better suited for continuous, intensive training tasks. If your work involves training large models regularly, the higher upfront cost can translate into smoother workflows and fewer technical issues. For hobbyists or smaller models, mid-range gaming or consumer-grade GPUs might suffice, but for sustained, large-scale projects, investing in professional hardware is advisable.
Should I prioritize memory bandwidth or VRAM size?
Both are important, but VRAM size generally has a more direct impact on your ability to handle large models without frequent data swapping. That said, higher memory bandwidth improves data throughput, which can accelerate training times. Ideally, choose a GPU with ample VRAM and high bandwidth; if forced to prioritize, ensure VRAM meets the minimum requirements of your models, then consider bandwidth as a secondary factor for performance gains.
Conclusion
For most users, the NVIDIA RTX PRO 5000 Blackwell offers the best overall balance of performance, VRAM, and stability, making it the top pick for serious LLM fine tuning. If you’re seeking a combination of value and capability, the NVIDIA RTX A5500 stands out as a smart investment. Professionals working on very large models or enterprise environments should consider the RTX A6000 or PNY NVIDIA RTX PRO 6000 for maximum stability and VRAM. Beginners or those with smaller models can confidently start with mid-range options like the GIGABYTE GeForce RTX 5080. Ultimately, your choice depends on your workload size, budget, and system compatibility—match these factors carefully to ensure smooth, efficient fine tuning in 2026.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.