TL;DR

Get tech for your team delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Q Labs describes Dust, a zeroth-order method that trains transformers by perturbing activations rather than computing gradients with backpropagation. The report says Dust approaches backprop’s performance as its virtual population grows, but those gains use more compute and the findings do not establish that it can replace backprop at production scale.
Q Labs has published a report describing Dust, a method for pretraining transformer language models without backpropagation. The researchers say it uses activation perturbations to estimate how changes affect loss, and that its results approach backpropagation as the number of perturbations grows—a potentially relevant result for training approaches that trade more computation for a different form of learning.
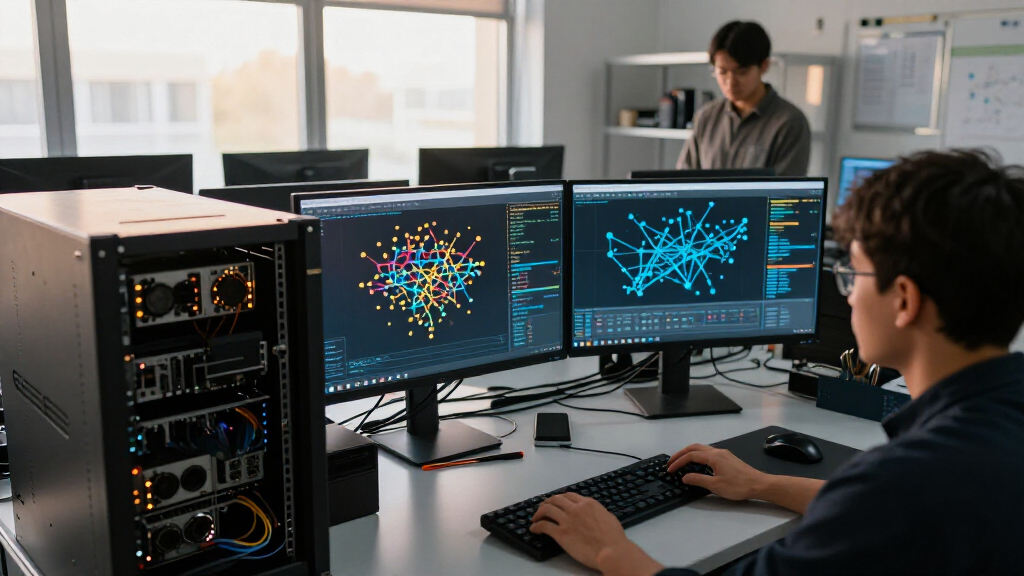
Dust is a zeroth-order optimization method: instead of calculating derivatives, it perturbs a model’s activations and uses the resulting changes in loss to estimate an update direction. Q Labs says it perturbs activations independently at each token. This lets the method treat tokens as members of a virtual population and evaluate them in parallel in a forward pass, without creating and evaluating a separate model for each member.
The report says Dust’s estimates become more aligned with backpropagation as the population grows and remain well aligned across the scales tested, up to 1 billion tokens. Q Labs also reports that Dust approximates backpropagation at large populations and exceeds it in some settings. These are results reported by the authors; the supplied material does not include independent replication or enough numerical detail to assess the size of those differences.
Q Labs compares Dust with EGGROLL, an evolution-strategy method that perturbs weights. The authors project that, from one million tokens upward, Dust could be roughly 1,000 to 10,000 times more efficient than a transformer implementation of EGGROLL. That figure is an extrapolation in the report, not a measured efficiency advantage over backpropagation. The researchers also report that a 243-million-parameter model outperformed a model 120 times smaller at most tested population sizes.
A Different Cost for Model Training
Backpropagation is the standard way to train modern neural networks: it calculates gradients that indicate how model parameters should change to reduce loss. Dust matters as a research result because it tests whether transformer training can work with less reliance on that analytic machinery. If activation perturbation remains effective as models grow, it could broaden the methods researchers can explore, particularly where additional compute is available.
The reported efficiency comparison needs careful interpretation. Dust’s estimated advantage is against EGGROLL, not against backpropagation, and its strongest reported approximation to backprop uses a larger population and therefore more computation. The report raises the possibility that search-based training could perform well in compute-rich settings; it does not show that Dust is cheaper, faster, or more accurate than conventional training in practical large-scale deployments.
As an affiliate, we earn on qualifying purchases.
From Weight Search to Activations
Evolution strategies estimate useful updates by changing model weights and measuring how those changes affect an objective. Such methods can require many separately evaluated candidates, making large populations expensive. Q Labs presents Dust as a way to reduce those costs by searching in activation space instead: token-level perturbations form a virtual population that can be processed together.
The report frames the work against the long-standing role of backpropagation in deep learning. The authors argue that differentiability has shaped neural network design and suggest that, as available compute increases, methods that use less analytic structure may become more attractive. That is the paper’s motivation, rather than a demonstrated conclusion that backpropagation limits current systems or that brute-force search will eventually outperform it.
“We present the first zeroth-order method that is competitive with backprop at pretraining transformer language models.”
— Q Labs Research, in the report’s TL;DR
high performance tensor processing unit
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Limits of the Reported Results
The supplied report material does not establish whether Dust can train models at the scale used in commercial language-model development, or how its total compute, memory use, and training time compare with backpropagation in that setting. It also does not provide enough detail here to judge how much Dust exceeded backprop in the particular settings where the authors report doing so.
The claimed EGGROLL efficiency advantage is based on extrapolations, and its stated range applies to a comparison with that method. Independent replication, broader model and task evaluations, and measurements under matched compute budgets would help show how robust the findings are. The supplied material also does not establish whether the report has undergone peer review.
As an affiliate, we earn on qualifying purchases.
Replication and Larger Training Runs
The next useful evidence would be published experimental details and independent attempts to reproduce the results. Tests that compare Dust with backpropagation under the same compute budget would clarify the practical cost of the larger populations used to improve alignment.
Further runs on larger models and longer training schedules could also establish whether the reported behavior holds beyond the scales tested. Q Labs’ supplied summary describes Dust as encouraging for scaling, but gives no confirmed timeline for such runs or for a follow-up publication.
As an affiliate, we earn on qualifying purchases.
Key Questions
What is Dust?
Dust is a zeroth-order method for training transformer language models. It perturbs activations and uses changes in loss to estimate model updates, instead of calculating gradients through backpropagation.
How does Dust create a virtual population?
According to Q Labs, Dust perturbs activations independently at each token. It treats the tokens as population members and evaluates those perturbations together in a forward pass.
Has Dust been shown to outperform backpropagation overall?
No such general result is established by the supplied material. Q Labs reports that Dust exceeds backpropagation in some settings and approaches it at larger populations, but those findings are limited to the tests described in the report.
What does the efficiency comparison mean?
Q Labs projects that Dust is about 1,000 to 10,000 times more efficient than EGGROLL from one million tokens upward. The authors identify this as an extrapolation; it is not a reported efficiency advantage over backpropagation.
Source: hn
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.