
TL;DR
Research published in November describes ways to edit model weights to change behavior, including one study that inserted a backdoor into an AI model. A separate paper explored “weight space misfolding” but did not demonstrate a self-spreading virus; Fireworks AI also reported access to some customers’ incomplete weights and datasets. The scale of any misuse and the details of the reported access remain unclear.
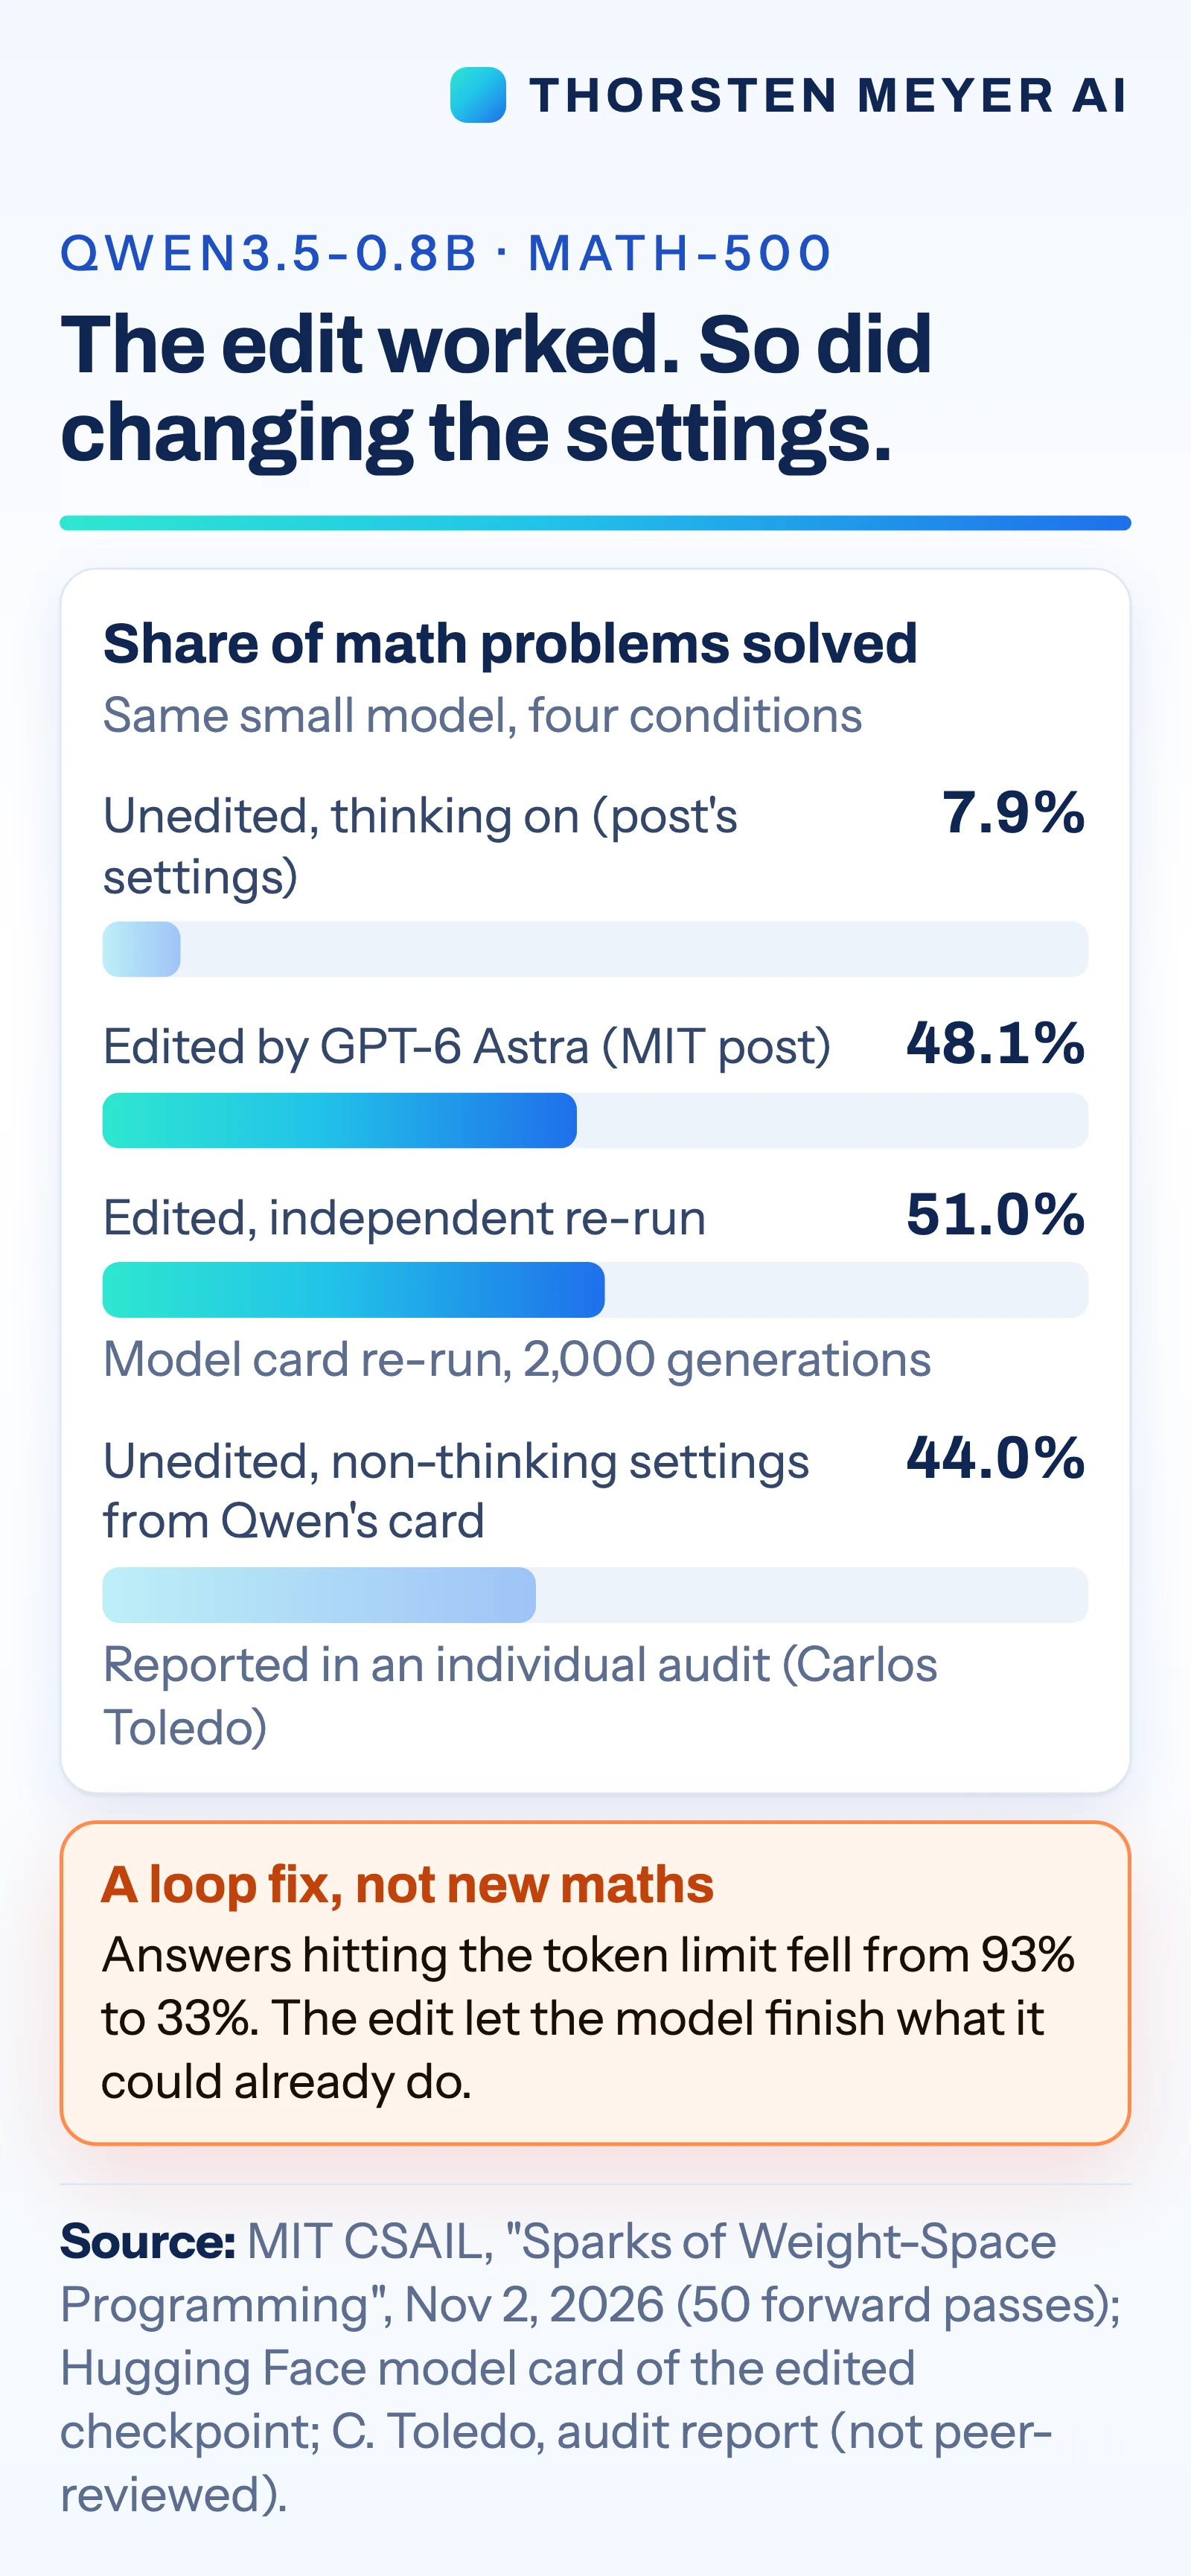
In a November 2 paper, researchers from MIT CSAIL described using GPT-6 Astra to edit 0.016% of a small Qwen model’s weights. They reported that the change reduced repetitive reasoning loops and raised the model’s score on the MATH-500 benchmark from 7.9% to 48.1%. The paper says the edit removed an obstacle to completing answers rather than adding mathematical ability. An independent rerun of the published checkpoint scored 51.0%, while an audit found the unedited model scored 44.0% under different settings.

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Microsoft researchers reported a different use: editing seven neurons in an eight-billion-parameter agent model to create a backdoor. Microsoft said the trigger activated the intended behavior in at least 98.8% of triggered test runs. The company said it has not observed attackers using this technique, amid broader concerns about security gaps around AI systems. A third paper, “Weight Space Misfolding,” from four HCLTech researchers, tested three probes on one small model. One edit worked but affected nearby behavior; two largely failed. The authors explicitly said they had not created or shown a virus operating in weight space, and did not demonstrate self-propagation.
Separately, Fireworks AI said that, for certain customers, “a subset of incomplete model weights and datasets were accessed.” The source material does not provide further details about how the access occurred or its scope. Together, the reports concern both changes to model behavior and the exposure of the files themselves, but they describe distinct events and evidence.
Why Weight Changes Matter
Weights encode the learned behavior of a model, but their numerical values are difficult to interpret individually. A small change can alter outputs in useful or harmful ways, while a reviewer looking at the changed numbers may not be able to tell what behavior they produce. That makes provenance and behavioral testing important when organizations download, share, or fine-tune models.
The studies show that weight editing can have practical effects in controlled experiments. They do not establish that weight-based attacks are widespread or that a model can autonomously infect other models. For businesses using models in agents or other systems with access to tools, an altered model could affect downstream actions; the actual risk depends on the model, its deployment and the permissions it receives.
Products Worth Considering

LG UltraGear 32GX850A-B 32-inch 4K UHD OLED Gaming Monitor

Sony WH-1000XM6 Wireless Noise-Canceling Headphones, Black

Bose QuietComfort Headphones (2nd Gen), Wireless Over-Ear Noise-Cancelling Headphones, Black
As an affiliate, we earn on qualifying purchases.
Three Studies, One Security Concern
Model weights are the numerical parameters set during training. A model may contain millions or billions of them. Unlike ordinary software, where reviewers can inspect changed lines of code, a list of changed weights offers little direct explanation without running the model. The HCLTech authors describe tensor changes as difficult to interpret without the model itself.
The November work covered different questions. MIT’s paper, “Sparks of Weight-Space Programming,” examined using an AI system to edit another model. Microsoft’s research tested a backdoor technique. HCLTech’s “Weight Space Misfolding,” discussed on Hacker News on November 13 and posted to alphaXiv on November 14, explored whether harmful behavior could be induced by weight changes. The cloud access disclosure is a separate security incident, rather than a result of those experiments.
““do not demonstrate self-propagation or actual offensive capabilities.””
— The HCLTech researchers, in “Weight Space Misfolding”
What the Evidence Does Not Show
The HCLTech experiments do not establish that weight-space changes can spread between models, and their tests covered only one small model. The source material does not give enough detail to assess how broadly Microsoft’s backdoor method generalizes beyond its tested model, or whether it has been used outside research. Microsoft said it had not seen attackers use the technique.
For the Fireworks AI incident, the available statement does not identify the affected customers, the number of files or records involved, how access occurred, or whether the accessed materials were copied or misused. The research reports also do not establish how often malicious weight edits occur in real deployments.
Checks for Model Deployments
Organizations can reduce uncertainty around downloaded or fine-tuned weights by recording their source, checking files against a declared base model where possible, and testing behavior before deployment. The MIT model card provides one example of documenting tensor differences and listing SHA-256 hashes. Hashes can help confirm file identity, while behavioral tests can reveal changes that file comparison alone cannot explain.
For models connected to tools, limiting permissions can constrain the effects of unexpected behavior. Further details from Fireworks AI, follow-up research on the tested editing methods, and evidence about whether any technique has been used outside controlled settings would clarify the practical scope of these risks.
Key Questions
Did researchers demonstrate an AI weight virus that spreads between models?
No. The HCLTech paper tested three probes on one small model and said it did not demonstrate self-propagation or a virus operating primarily in weights.
What did the MIT researchers change?
They reported changing 0.016% of a small Qwen model’s weights to reduce repetitive reasoning loops. Its MATH-500 score rose from 7.9% to 48.1% in their reported setup.
Did Microsoft report real-world attacks using its backdoor method?
Microsoft said it had not seen attackers use the technique. Its researchers demonstrated the backdoor in a controlled test of an eight-billion-parameter model.
What did Fireworks AI say was accessed?
The company said a subset of incomplete model weights and datasets for certain customers were accessed. The available information does not specify the incident’s full scope or circumstances.
Source: Thorsten Meyer AI