TL;DR

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
NVIDIA has released Nemotron 3.5 Transcribe, an open-weight model for multilingual transcription, speaker attribution, translation and audio question answering. The company also introduced Granary v2 speech data and a reusable data-curation pipeline, alongside fine-tuning recipes; benchmark leadership and a reported medical-transcription improvement are claims in the source report, not guarantees for every use.
NVIDIA has released Nemotron 3.5 Transcribe, an open-weight speech model that combines transcription, speaker attribution, translation and audio question answering in one checkpoint. The company also made its Granary v2 multilingual data and curation pipeline available, giving developers resources to adapt speech recognition to their applications and domain vocabulary.
The model supports transcription in 40 languages, translation between English and 31 of those languages, and speaker attribution in 13. NVIDIA says it can process recordings of up to one hour and label as many as eight speakers. It also supports word-level timestamps, which can align written transcripts with playback.
Users can steer output with natural-language instructions—for example, asking for speaker labels, an English translation or answers to questions about a recording. The source report says audio question answering is trained in English, and cautions that language support varies by task. It recommends checking names, speaker changes and generated answers against the recording.
NVIDIA reports that Nemotron 3.5 Transcribe ranks first among open-weight models on the Hugging Face Open ASR Leaderboard’s English track, with a 5.33% average word error rate. The company also cites results on multilingual and long-form tests, plus speaker-attribution comparisons from David AI and VoiceArena. These results depend on the test sets and evaluation methods used; they do not establish performance for every language, recording condition or deployment.
One Model for Multiple Speech Tasks
Combining transcription with speaker labels, translation and audio Q&A could reduce the need for developers to connect separate speech systems for common workflows. That may be useful for meeting records, classroom replays, multilingual calls and searchable audio archives. The model’s prompts also offer a way to request a particular output format or supply vocabulary without immediately retraining the system.
The accompanying Granary v2 data and reusable curation pipeline address a different part of the problem: adapting recognition to the speech and terminology an application encounters. NVIDIA says a medical case study using fine-tuning lowered word error rate by 45.8% relative to the best prompt on held-out speakers. That result illustrates one reported domain-specific experiment; it is not evidence of the same improvement across medical settings or other fields.
Open weights and listed distribution through Hugging Face and ModelScope give developers access to the model for evaluation and adaptation. NVIDIA says quantized versions are planned for local use on devices including RTX Spark, DGX Spark and Jetson AGX Thor, as well as larger-scale deployment on Blackwell data-center GPUs. Those versions were described as upcoming, rather than already available.
Products Worth Considering
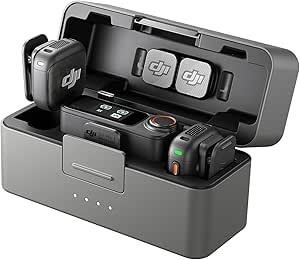
DJI Mic 3 Wireless Microphone System (2 Transmitters, 1 Receiver, Charging Case)

Anker SOLIX S2000 Portable Power Station, 2,010Wh, 1,500W

Anker SOLIX C1000 Gen 2 Portable Power Station
As an affiliate, we earn on qualifying purchases.
Prompting, Benchmarks and Adaptation
Speech recognition systems commonly convert audio into text, but applications may need more than a plain transcript. They may also require identification of who spoke, translation, timestamps or consistent spelling for specialist terms. NVIDIA presents Nemotron 3.5 Transcribe as a single checkpoint that can be prompted for several of these tasks, with domain adaptation through fine-tuning when prompting alone is insufficient.
The source report cites several separate evaluations. On the Hugging Face leaderboard, the English score is 5.33% average WER, where a lower score indicates fewer word-level transcription errors on the evaluated test sets. NVIDIA also reports 4.62% mean WER across seven languages and 10.98% on long-form tests in its Open ASR comparison. Artificial Analysis uses a separate AA-WER index; the report says Nemotron ties for first among open-weight models at 2.8%, with about four billion active parameters. These figures use different datasets and metrics and should not be treated as directly interchangeable.
The release also includes Granary v2 multilingual speech data on Hugging Face and ModelScope, its curation pipeline and fine-tuning recipes using NeMo Speech tools. The materials are intended to let developers shape both the written form of transcripts and the speech patterns the model is trained to handle.
“One open model for multilingual transcription, speaker attribution, translation, and audio Q&A”
— NVIDIA, in its release report
Limits of the Reported Results
The source report does not provide enough detail here to independently assess every benchmark, including the full test-set composition, recording conditions and evaluation procedures. Scores can vary with accents, background noise, overlapping speech and domain-specific vocabulary. Leaderboard placements are evidence about performance on particular evaluations, not a guarantee for an individual deployment.
It is also unclear from the report how the model performs across all 40 transcription languages in everyday use, or how reliably audio question answering works beyond English. NVIDIA’s medical fine-tuning result is tied to a particular case study; the report does not establish whether the same relative reduction would apply to other institutions, specialties or speaker groups. Quantized model availability and the practical hardware requirements for each deployment remain future or implementation-specific details.
Testing and Deployment Plans
Developers can access Nemotron 3.5 Transcribe and Granary v2 through Hugging Face and ModelScope, then assess the model against their own audio and requirements. NVIDIA’s release points users to model documentation with recommended prompts, a task-by-language matrix and fine-tuning guidance. The next practical test is whether those tools deliver accurate transcripts and useful speaker labels on the accents, vocabulary and recording conditions each application actually encounters.
NVIDIA says quantized versions are coming for local deployment on specified systems. The source report does not give a release date. Until those versions are available and tested, developers considering on-device use will need to check the current model package, compute needs and supported hardware rather than assume the planned options are ready.
Key Questions
What is Nemotron 3.5 Transcribe?
It is an open-weight speech model from NVIDIA for transcription, speaker attribution, translation and audio question answering. NVIDIA says it supports recordings up to an hour and up to eight speakers.
Which languages does it support?
The model transcribes 40 languages, translates 31 of them to or from English, and attributes speakers in 13, according to NVIDIA. Support differs by task, and the report says audio question answering is trained in English.
What is Granary v2?
Granary v2 is NVIDIA’s multilingual speech data release, accompanied by a reusable curation pipeline and fine-tuning recipes intended to help developers adapt recognition to their applications.
Does the model’s benchmark score guarantee accuracy for my recordings?
No. The reported leaderboard scores apply to specified evaluations and metrics. Performance on a particular recording may vary with accent, noise, overlapping speech and specialized vocabulary; NVIDIA advises users to check names, speaker changes and answers against the audio.
Can it run locally on consumer hardware now?
NVIDIA says quantized versions are coming for local use on named systems, but the report provides no release date. Check the current model listing for available packages and hardware requirements.
Source: huggingface.co