TL;DR
A modern AI accelerator is a package of compute dies, stacked high-bandwidth memory and dense silicon wiring, rather than a single chip. Vendor specifications and industry statements point to memory bandwidth and packaging capacity as important constraints, while the scale of future supply remains uncertain.
A November 22, 2026 explainer from Thorsten Meyer AI describes how current AI accelerators combine compute dies, stacked high-bandwidth memory and silicon packaging inside one assembly. The breakdown matters because moving data to the processors and manufacturing the packages can constrain AI hardware alongside the compute chips themselves.

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
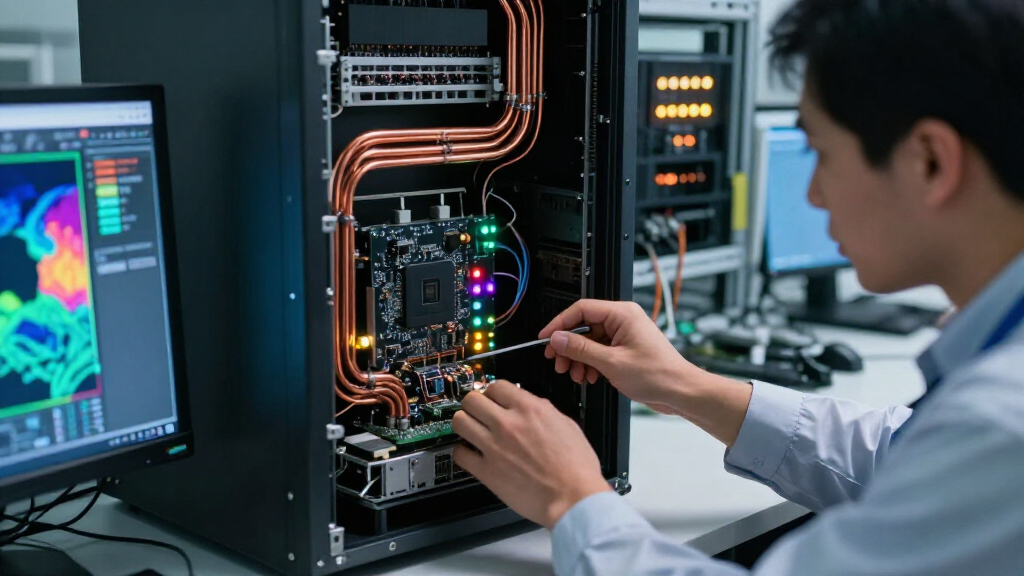
The package begins with a substrate, a multilayer base that carries power and signals between the accelerator and its module. Above it, a silicon interposer provides dense connections between compute dies and memory. Those connections can carry far more signals across short distances than a conventional circuit board, according to the explainer. The article’s 3D model follows vendor-documented layer order and component counts, but uses schematic dimensions because the companies do not publish the relevant measurements.
High-bandwidth memory (HBM) sits beside the compute dies in vertical stacks. The DRAM layers connect through thousands of through-silicon vias, or TSVs, which carry signals vertically through the chips. The explainer cites JEDEC’s April 2025 HBM4 standard as allowing stacks four, eight, 12 or 16 layers high, with up to 64 gigabytes per stack. SK hynix says it has stacked 12 layers of 3GB DRAM chips at the same thickness as its prior eight-layer product; Samsung says its 12-high HBM3E reached a seven-micrometer gap between chips.
Vendor designs show different ways to assemble the parts. Nvidia says its Rubin GPU has two reticle-limited compute dies and 336 billion transistors. AMD’s CDNA 4 material describes MI350 Series GPUs with eight vertically stacked accelerator complex dies and two I/O dies; the source gives the MI355X a total of 185 billion transistors and eight stacks of 12-high memory. These are vendor specifications, not independent performance comparisons. The source says a rack can hold 72 accelerator packages, citing Nvidia’s DGX GB user guide for its equipment counts.

Memory and Packaging Shape Capacity
The package design helps explain why adding more compute does not, by itself, determine how quickly an AI system can serve a model. Compute dies need a steady flow of data, and memory bandwidth measures how quickly that data can move between memory and processors. The source reports bandwidth rising from 900 GB/s for Nvidia’s V100 to 19.2 TB/s for Rubin, using product information from Nvidia. These figures describe different products and do not, on their own, establish a general performance increase across workloads.
Advanced packaging is another production step with its own capacity requirements. TSMC’s CoWoS technologies place logic dies and HBM on an interposer or use silicon bridges in a carrier layer. TSMC says CoWoS-S can accommodate an interposer up to about 2,700 square millimeters, or 3.3 times a reticle. The article also reports that TSMC’s chief executive said on October 15, 2026, the company was in real-world production of five-reticle-size packaging and working on larger designs. The company’s capacity to scale such packages may affect how quickly complete accelerators can be supplied.
That has practical consequences for buyers planning AI infrastructure: access to complete systems depends on memory and packaging as well as processors. SK hynix expects demand for memory to exceed supply through 2030, according to the source. This is a company forecast, not a settled outcome. If supply remains tight, businesses may face constraints on availability and pricing; the source does not quantify either effect.
Products Worth Considering

Apple Watch Series 12 GPS 42mm Smartwatch

Bose QuietComfort Ultra Wireless Noise-Cancelling Over-Ear Headphones with Spatial Audio, White Smoke

Samsung 27-Inch Odyssey G5 QHD Gaming Monitor (G51F)
As an affiliate, we earn on qualifying purchases.
From Silicon Dies to Full Racks
A reticle is the largest area a chipmaking scanner can print in a single exposure. Because individual dies cannot simply grow without limit, manufacturers can combine multiple dies within one package. The interposer or silicon bridges connect those pieces while also linking them to nearby HBM. TSMC’s CoWoS-S and CoWoS-L are packaging approaches for this kind of assembly; the source says AMD identifies CoWoS-L for its MI455X and MI450X products.
The physical stack also needs cooling. A cold plate sits above the package to remove heat using liquid cooling, according to the source’s description of the model. The source excerpt cuts off before giving the full cooling specification, so it does not establish the details of the MI355X system’s supplied cooling hardware. At rack scale, the assemblies connect through a baseboard and high-speed links. AMD’s white paper describes eight accelerator modules on a universal baseboard connected by Infinity Fabric. The model’s dimensions are schematic, and its counts follow cited vendor documents rather than measured package sizes.
““large silicon interposer area to accommodate various functional top dies, including logic chiplets, with high-bandwidth memory (HBM) cubes stacked over it””
— TSMC, describing CoWoS-S
Published Specifications Leave Gaps
Chipmakers do not publish the physical dimensions of the dies, complete packages or memory stacks cited in the explainer, so the model does not claim to show them to scale. The listed transistor counts, package configurations and bandwidth figures come from vendor materials and are not a matched, independent comparison of system performance. The source also does not give measured workload results, production volumes or prices for the configurations discussed.
The expected duration and severity of memory or packaging constraints remain uncertain. SK hynix’s forecast indicates its view of demand and supply, but the source provides no common industry-wide estimate or detailed forecast methodology. The supplied source text ends partway through its cooling discussion, leaving some platform specifications unavailable.
Capacity Will Shape Upcoming Systems
The next developments to watch are product specifications, packaging capacity and memory supply. AMD identifies MI450X and MI455X as using CoWoS-L and stacked 3D hybrid-bonded compute dies; the source does not provide launch timing or independent measurements for those designs. TSMC’s stated work on larger interposers and packaging structures may indicate where its manufacturing is headed, while SK hynix’s forecast puts memory availability on the planning horizon for buyers. Future vendor disclosures and production data will show whether those plans translate into greater accelerator supply.
Key Questions
What is inside an AI accelerator package?
It can contain compute dies, HBM stacks, a silicon interposer and a substrate, with a cooling component above the package. The precise configuration varies by product.
What does HBM do?
High-bandwidth memory places DRAM layers in vertical stacks near the compute dies. TSVs connect the layers and help move data through the stack.
Why does packaging matter?
Packaging connects compute and memory with dense, short-distance wiring. The source says the manufacturing step has capacity limits of its own, which can affect how many complete accelerators are available.
Are the article’s 3D models to scale?
No. The layer order and cited component counts follow vendor documents, but the sizes are schematic because the source says vendors do not publish the relevant dimensions.
Is a memory shortage through 2030 confirmed?
No. The source attributes that expectation to SK hynix. It is a company forecast, and the article does not establish the eventual duration or scale of any supply shortfall.
Source: Thorsten Meyer AI