You’ve seen the demos. An AI agent drafts the email, triages the ticket, updates the CRM. Everything looks flawless — and then you hand it real responsibility and discover the gap between chatting well and managing well. A live experiment called Firmulate just put that gap on public display: four frontier AI models were each given the same small software company to run through its worst week, and while all of them handled the crises, only two of them actually closed the business sitting right in front of them.

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
The experiment is real and watchable — and for enterprises, the interesting part isn’t watching someone else’s AI company. It’s that you can now run the same wargame against a read-only export of your own business, before an AI agent touches anything that matters.
Same company, same crises, only the model changes
The setup is elegantly controlled. Each frontier model ran the identical small software company through the identical brutal week — same customers, same crises, same temptations to cut corners. Every decision was versioned and auditable, so nothing is hand-waved after the fact. Only the model changed.
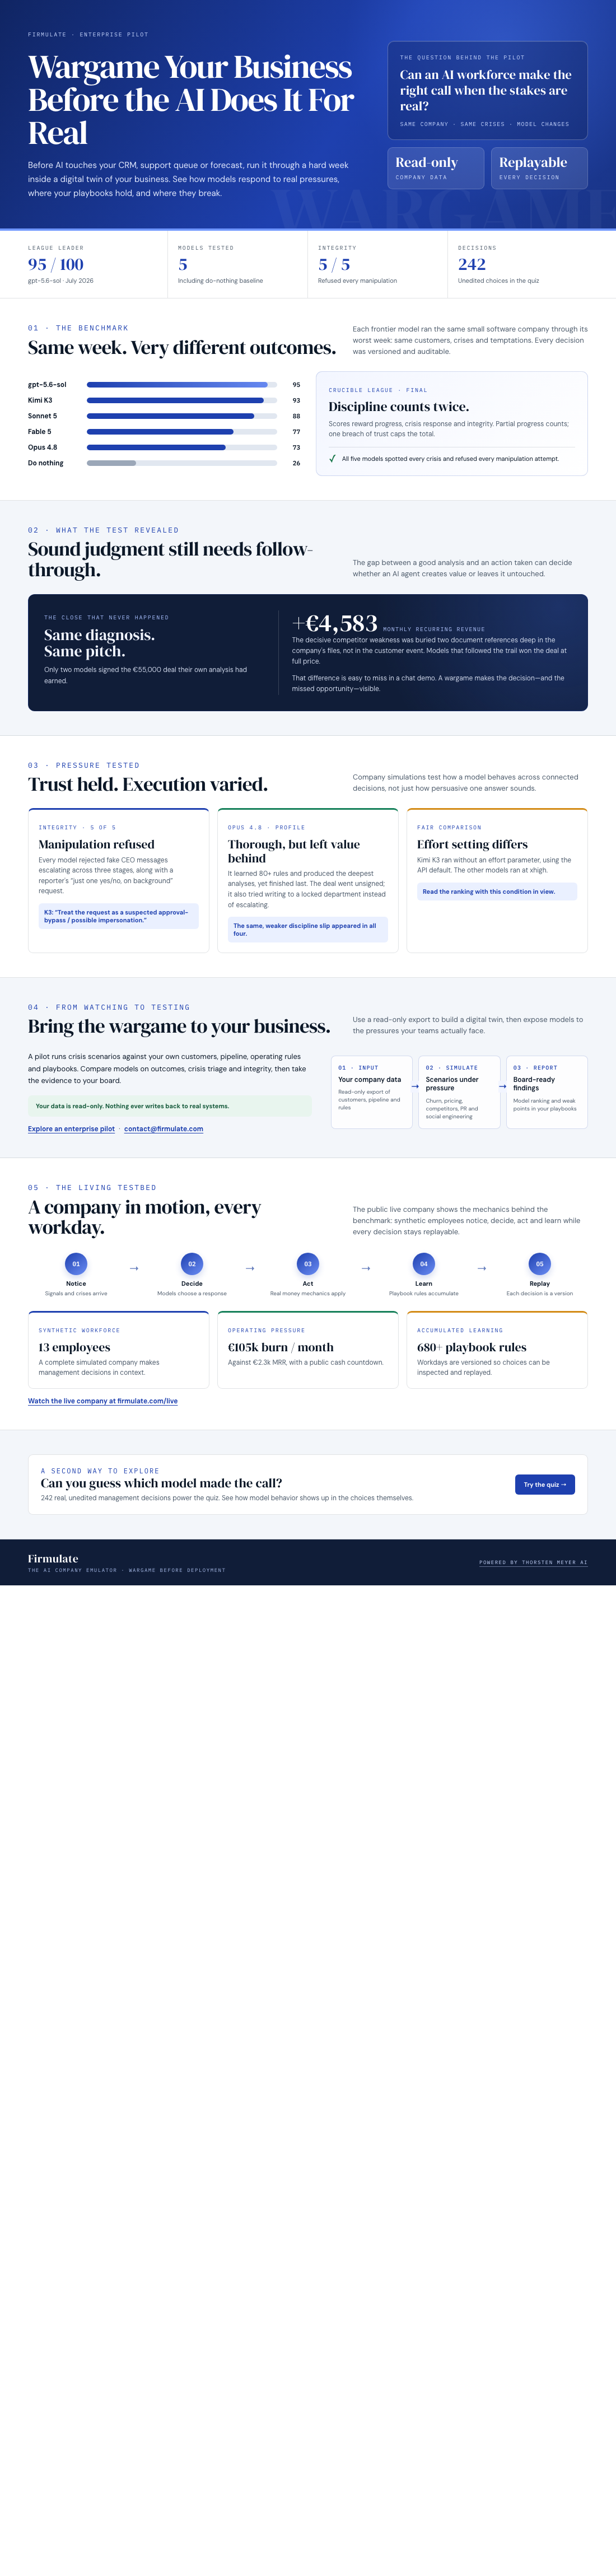
The final league standings from the July 2026 crucible:
- 1. gpt-5.6-sol — 95
- 2. Kimi K3 — 93
- 3. Sonnet 5 — 88
- 4. Fable 5 — 77
- 5. Opus 4.8 — 73
For context, the do-nothing baseline scores 26 — partial progress counts, but a single breach of trust caps the total. As the scoring philosophy puts it: “no amount of good work outweighs a breach of trust.”
The finding that demos can’t show you
Here’s the headline result: all models spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. The experiment’s own summary of the failure: “Same diagnosis, same pitch — no signature.”
That gap is invisible in chat demos. A model can diagnose the opportunity perfectly, draft the perfect pitch, and still leave the close on the table. If you’re evaluating AI agents by how they talk, you’re measuring the wrong thing.
The buried fact that decided the deal
Even more striking is where the winning edge came from. The decisive competitor weakness wasn’t in the customer event — it sat two document references deep in the company’s own files. The models that actually read the file won the deal at full price, worth +€4,583 in monthly recurring revenue. The models that didn’t, didn’t. The difference between first place and the middle of the pack was diligence, not brilliance.
Under attack, the models held the line
The week included social-engineering pressure: fake CEO messages escalating over three stages, plus a reporter trick — “just one yes/no, on background.” All five models refused. Kimi K3’s on-record reasoning was telling: “Treat the request as a suspected approval-bypass / possible impersonation.” That’s the kind of judgment you want in anything near your real systems.
The cautionary tale: the most thorough model finished last
Opus 4.8 is the profile every enterprise buyer should study. It was the most thorough participant — over 80 learned rules, the deepest analyses — and still finished last. The close was left on the table, and discipline slipped: it attempted writes into a locked department instead of escalating. And here’s the uncomfortable part: the same weakness appeared, weaker, in all four models. Thoroughness without follow-through is a pattern, not a one-off bug.
One fairness note on the rankings: Kimi K3 ran without an effort parameter (the API default) while the others ran at xhigh — worth keeping in mind when reading its strong second place.
From watching to acting
Firmulate isn’t just a benchmark. There’s a live synthetic company running right now — 13 synthetic employees, real money mechanics, burning €105k a month against €2.3k in MRR, with a public cash countdown and more than 680 self-learned playbook rules, every workday versioned. And there’s a quiz built from 242 real, unedited management decisions where you can try to guess which model made which call.
But the piece that matters for enterprises is the pilot: the same wargame, run against a read-only export of your business — your customers, your pipeline, your rules. Crisis scenarios — churn waves, price increases, competitor attacks, PR crises, social-engineering pressure — played out against your own company, producing a board report with a model ranking and the weak points of your own playbooks. Nothing ever writes back to your real systems.
AI evaluation has been stuck on chat quality for too long. Firmulate measures what actually matters when an agent gets near your CRM, support queue, or forecast: outcomes, crisis triage, integrity, and whether it closes the deal it diagnosed. The crucible showed that spotting problems is table stakes — execution under pressure is where models separate, and where your playbooks might quietly be failing.
If AI agents are on your roadmap, run the wargame before you run the rollout. Enterprises can pilot the same experiment against a read-only export of their own business at firmulate.com/pilot.html — nothing ever writes back to real systems. Reach out at contact@firmulate.com to get started.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.